My final year project: one place for every student query, whether it comes from the web, email or WhatsApp.
The problem. A university gets hundreds of student queries a day. Students don’t know which department to ask, so emails land in the wrong inbox, replies are slow, and nothing chases a query once it is forgotten.
My part. I built it end to end. A FastAPI backend classifies each query with Gemini through LangChain, falls back to a model on Groq when Gemini fails or is unsure, and strips personal details before any text reaches a model. It routes the query to whoever handles it, drafts a reply that a person approves, and escalates what waits too long. n8n runs the Gmail intake and the schedules, on an Oracle Cloud VM behind Caddy, with the React app on Vercel.
Orchiver
A personal archive for Markdown, LaTeX, Word and PDF files, with a history of every edit and a copy in the cloud.
The problem. My writing lives in four formats, in folders on one PC. I wanted each file’s history, conversions between the formats, and a backup off the machine, without handing the files to a service that keeps them in its own shape.
My part. A TypeScript monorepo. The React app works on the real folder through the browser’s File System Access API, with an editor and live preview for Markdown and LaTeX and a revision on every save. A three-way sync to Cloudflare R2 keeps every version it replaces and finishes cleanly after a crash halfway through. A small Fastify server converts between the formats with Pandoc and LibreOffice.
An open-source MCP server that hands Figma designs to AI coding tools, without rate limits.
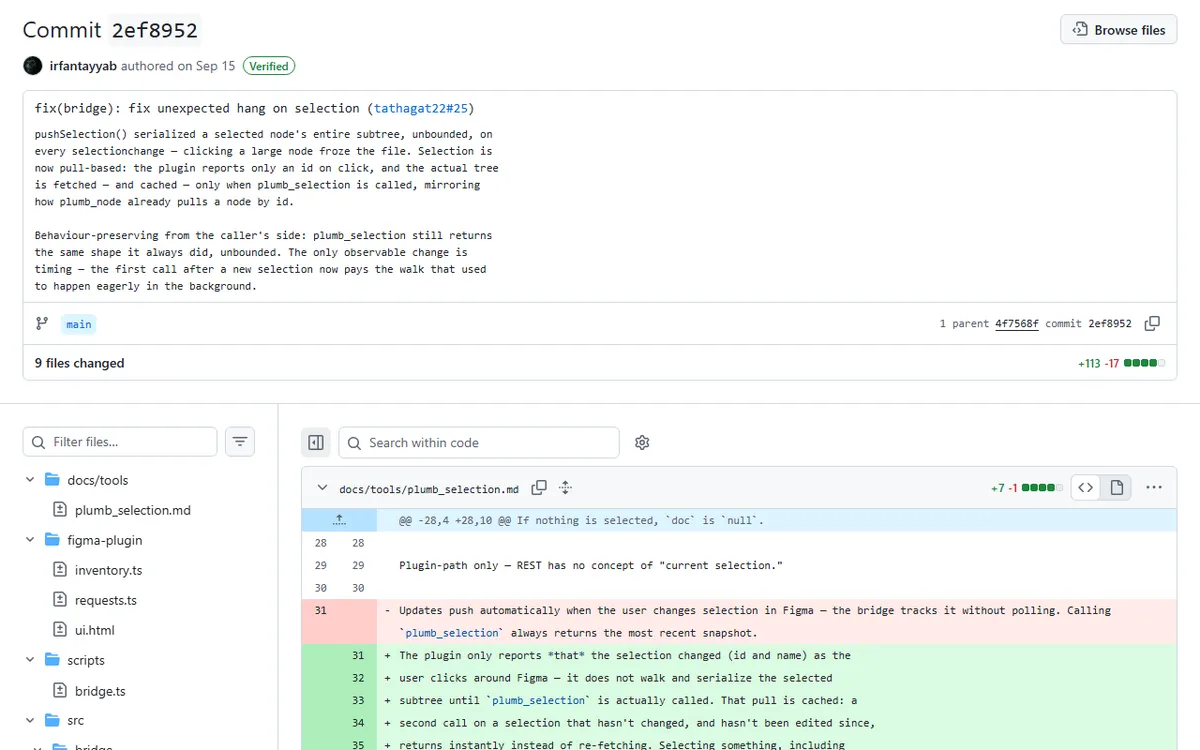
The problem. Clicking a large frame froze the Figma file. The plugin serialized the selected node’s whole subtree on every selection change, whether anything had asked for it or not.
My part. I made selection pull-based. The plugin now reports only the node’s id on a click, and the tree is walked, and cached, only when a tool asks for it, the way it already fetched a node by id. Callers get the same result as before, and the fix merged with all 955 tests passing.
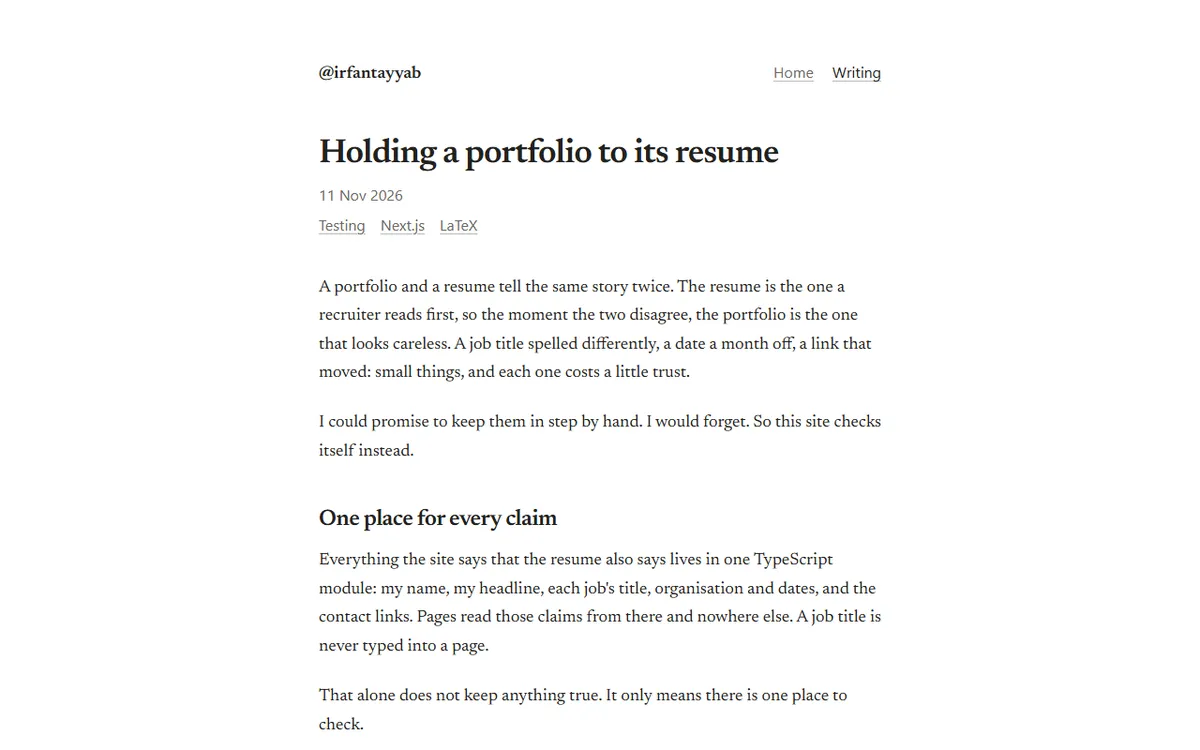
A portfolio and a blog, served as static files, with its claims held to the resume by a test.
The problem. A portfolio that repeats the resume adds nothing, and one that drifts from it costs trust.
My part. A Next.js static export on Cloudflare, deployed from GitHub Actions only once every check passes, with a preview for each pull request. A test holds every job title, date and contact link on the site to the resume’s LaTeX source and its PDF, and a hash ties the PDF to the source it was built from. Every page is loaded in a real browser without JavaScript and scanned by axe in both themes.